Your sales team opens a promising account and finds three employee counts, two industries, and an outdated executive title. A data provider can fill the gaps in seconds. However, letting it overwrite trusted CRM fields just as quickly can create a larger problem.
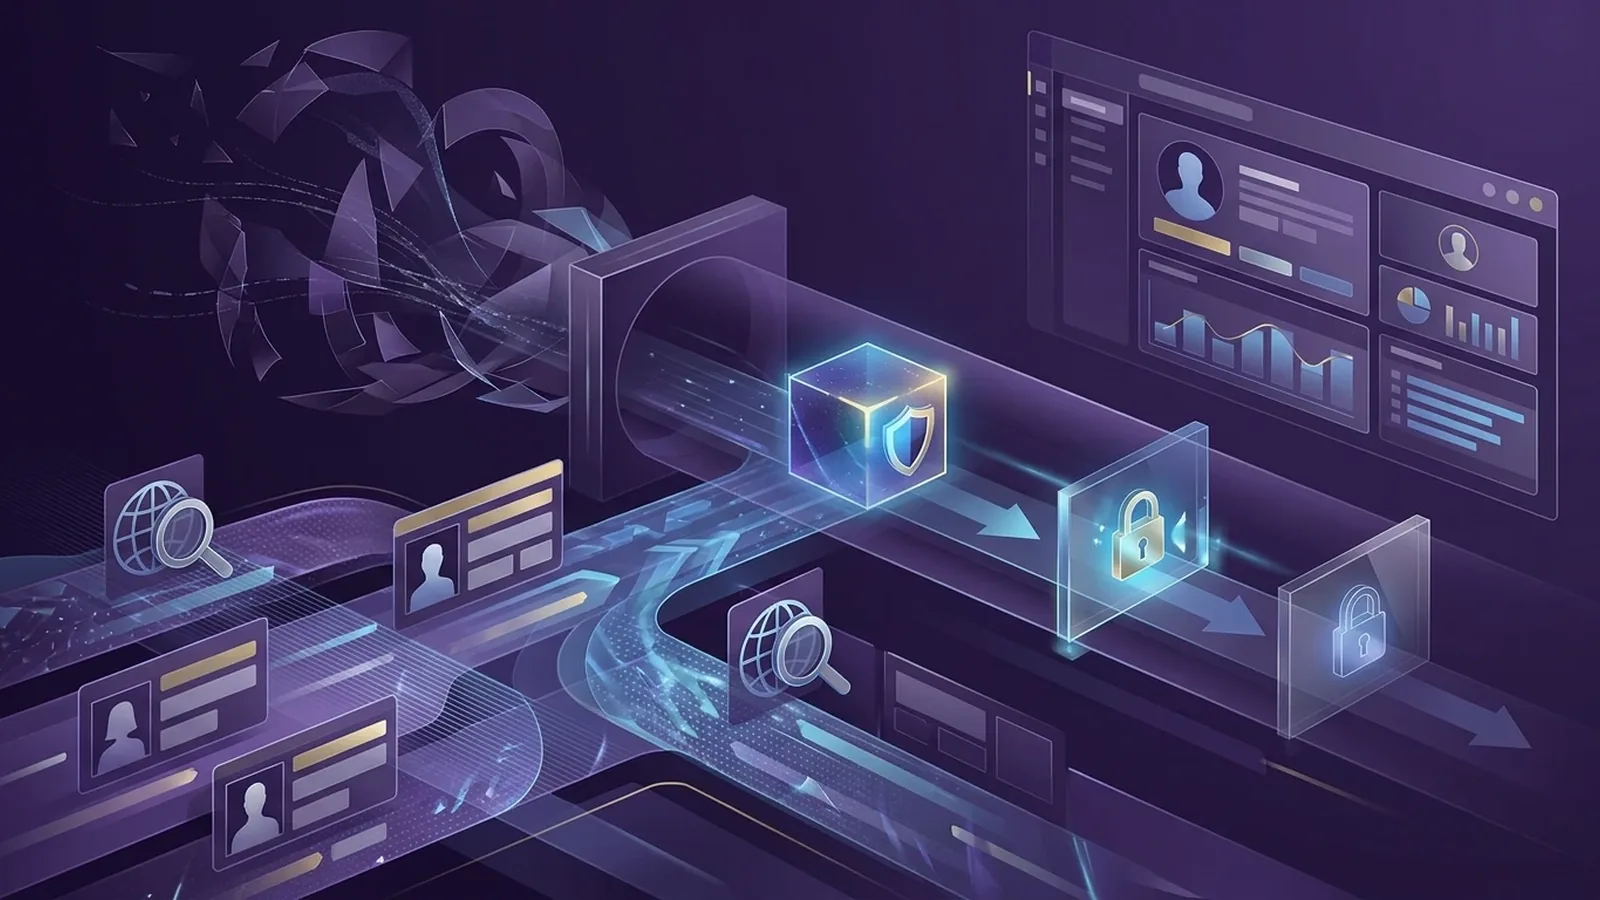
A safe CRM data enrichment loop does more than retrieve missing values. It identifies records, checks several sources, normalizes results, applies field-level rules, and sends uncertain changes to a human. Only approved values reach the CRM.
This article gives RevOps teams a practical design for that loop. You can use it to improve record completeness without turning your CRM into a collection of unexplained third-party guesses.
In This Article You’ll Learn
- How to design a seven-stage enrichment workflow with controlled CRM write-back.
- Which fields are suitable for automatic updates and which need human review.
- How to define source precedence, confidence thresholds, and overwrite protection.
- How to handle conflicting values, duplicates, stale records, and provider failures.
- Which metrics reveal whether your enrichment loop is accurate, useful, and affordable.
- How to launch a narrow pilot before expanding enrichment across the revenue database.
Why One-Time Enrichment Is No Longer Enough
CRM records decay because the organizations and people behind them keep changing. Employees change roles. Companies merge, hire, contract, rebrand, and move into new markets. A record that was accurate six months ago may now mislead routing, scoring, segmentation, and account planning.
Traditional enrichment projects usually run as periodic database cleanups. RevOps exports a list, sends it to a provider, and imports the returned file. That can improve coverage temporarily. Yet it rarely provides durable controls for source conflicts, field ownership, or future changes.
Continuous enrichment treats data quality as an operating workflow. For example, HubSpot documents enrichment that can run manually, automatically for new records, or continuously for previously enriched records. Regardless of platform, the important shift is from a lookup event to a governed loop.
A loop can react when a lead enters the CRM, an account reaches a target stage, or a trusted field becomes stale. It can also choose different providers by record type. Most importantly, it can decide not to write a value when the evidence is weak.
If you need help connecting triggers, validation, routing, and CRM actions, AI workflow automation provides a useful implementation path.
The Seven-Stage CRM Enrichment Loop
A mature enrichment workflow has seven stages: trigger, identify, retrieve, normalize, validate, review, and write back. Keeping those stages separate makes problems easier to diagnose. It also prevents retrieval logic from silently becoming update authority.
1. Trigger the Workflow for a Defined Reason
Do not enrich every record on every change. Start with events tied to a business decision. Useful triggers include a new target account, a lead reaching a scoring threshold, or an account entering an active sales stage.
Time-based triggers also help. For example, you might review an employee count after 180 days. A verified work email may receive a longer refresh interval because changing it carries greater operational risk.
2. Identify the Person or Company
Before retrieving data, confirm that the workflow has identified the correct entity. A company domain is usually stronger than a company name. A person’s name plus employer domain is safer than a name alone.
Ambiguous identities should enter an exception queue. Never let the agent guess between similarly named companies or contacts. A false match can contaminate many downstream fields at once.
3. Retrieve Data From Approved Sources
Define which providers may supply each field. One source may perform well for company attributes, while another offers better contact coverage. Provider fallback can improve completeness, but it also increases cost and conflict frequency.
The retrieval layer should capture the provider, query time, returned value, and supporting identifiers. Without that provenance, your team cannot explain why a field changed or assess whether the source remains dependable.
4. Normalize Before Comparing Values
Providers often express the same fact differently. One may return “VP Sales,” while another returns “Vice President of Sales.” Employee counts may arrive as exact numbers, ranges, or text labels.
Normalization converts those values into your CRM’s accepted formats. It should standardize country codes, job levels, industry labels, phone formats, domains, and employee bands. Only then can the workflow compare values fairly.
5. Validate With Field-Level Rules
Validation should answer three questions. Is the value structurally valid? Is the source allowed for this field? Is the new value strong enough to replace what already exists?
Each candidate update should receive a confidence score based on identity strength, source reliability, agreement among providers, freshness, and validation results. Confidence is not universal. A score acceptable for industry classification may be inadequate for a work email.
6. Route Uncertain Changes for Review
Human review should focus on consequential or ambiguous changes. Reviewers need the current value, proposed value, sources, confidence, and reason for escalation. A bare approve button is not enough.
A sensible starting policy is:
- Automatically fill reversible, empty fields when confidence is at least 90 percent.
- Queue conflicting values when confidence falls between 70 and 89 percent.
- Reject values below 70 percent without changing the CRM.
- Always review changes to owner, consent, lifecycle stage, or verified contact details.
These thresholds are examples, not universal benchmarks. Tune them using review outcomes from your own records.
7. Write Back With an Audit Trail
Approved updates should carry operational metadata. Record the source, retrieval time, confidence, workflow version, previous value, and update reason. Store this information in dedicated properties or an external audit log.
Field-level permissions should restrict what the workflow can change. A custom data agent should not inherit broad CRM administrator rights. Teams exploring source selection and controlled actions can review custom AI agents for relevant design considerations.
Use Source Precedence and Overwrite Policies
Source precedence tells the workflow which evidence wins. Overwrite policy determines whether a winning candidate may replace the existing CRM value. You need both rules because the most credible external source should not always override trusted first-party data.
Use the following field-level model as a starting point:
- Work email: Prefer a verified first-party email. Never replace it solely because an external provider returns another address.
- Job title: Prefer recent first-party confirmation, then an approved professional source, followed by enrichment databases with matching employer evidence.
- Company domain: Prefer a verified website domain. Route redirects, acquisitions, and parent-company conflicts to review.
- Employee count: Store the source date and use a consistent band. Avoid pretending that an estimated value is exact.
- Industry: Map provider labels into your taxonomy. Allow automatic updates only when the current field is empty or untrusted.
- Phone number: Validate format and country. Preserve consent status separately and never infer consent from phone availability.
Protect first-party values with a trust flag. For example, a sales representative can mark a title as customer-confirmed. The enrichment workflow may then suggest an alternative, but it cannot replace that field automatically.
Also define source expiration. A provider result from yesterday should not have the same weight as one retrieved two years ago. Freshness requirements should vary by field because job titles decay faster than company domains.
A Practical RevOps Scenario
Suppose a target account enters an active opportunity stage. Its industry field is empty, while the primary contact’s title is “Director of Operations.” The enrichment loop queries two approved providers.
Both providers classify the company as industrial software. The company domain matches, and the taxonomy mapping succeeds. Confidence reaches 94 percent. Because the industry field is empty and reversible, the workflow writes the normalized value automatically.
The title result is less clear. One provider returns “VP Operations,” while the other returns “Director of Operations.” The CRM value came directly from a recent sales conversation. The loop therefore protects the existing title and sends the proposed change to review.
The reviewer sees each source, retrieval date, employer match, current title, and proposed title. They reject the change because first-party information is newer. That decision becomes feedback for future scoring.
This example shows why record-level confidence is insufficient. One record can contain a safe industry update and a risky title change. Decisions must happen at the field level.
What Most Teams Get Wrong
They Begin With a Bulk Update
A database-wide update makes it difficult to isolate defects. It can also consume provider credits before you know whether the returned values help a real workflow. Start with a narrow segment and a small field set.
They Treat Missing and Conflicting Data the Same
Filling an empty industry field is different from replacing a verified industry. Overwrites require stronger evidence and clearer ownership. Your workflow should distinguish additions, corrections, and refreshes.
They Store Values Without Provenance
A field without a source or timestamp quickly becomes another mystery. When values conflict later, nobody knows which one deserves trust. Provenance should accompany every automated update.
They Use One Confidence Score for Every Field
Fields have different consequences. An inaccurate employee band may affect segmentation. An incorrect email can damage deliverability and sender reputation. Match thresholds to business impact.
They Forget Duplicate Handling
Enrichment may uncover a new domain or email that already exists elsewhere in the CRM. Check uniqueness constraints before write-back. Otherwise, the workflow can create duplicates or merge unrelated entities.
They Skip Rollback Planning
Even a carefully designed provider can return bad data. Keep previous values and batch identifiers so you can reverse affected updates. A cleanup plan written after an incident is usually too late.
Risks and Tradeoffs
Continuous enrichment improves freshness, but it introduces recurring cost and operational complexity. More providers can raise coverage. However, each additional source creates more conflicts, mapping rules, and failure modes.
Automatic updates reduce manual work, but strict automation can amplify an incorrect match. Human review lowers that risk, although a poorly designed queue can overwhelm RevOps. Reserve review for high-impact changes and uncertain identities.
AI can help reconcile labels and interpret inconsistent source formats. Still, deterministic rules should govern permissions, protected fields, and write-back. A language model should not decide whether it may alter consent, ownership, or lifecycle status.
Privacy is another concern. Collect only data needed for a defined business purpose. Apply retention rules, access controls, and regional requirements. Availability from a provider does not automatically make every attribute appropriate to store.
Finally, enrichment can create false precision. Employee counts and revenue estimates are often modeled rather than verified. Preserve ranges and source labels when exact values are unsupported.
Measure the Loop as an Operating System
Record completeness alone does not prove the workflow is useful. A loop can fill many fields while introducing errors or unnecessary costs. Track quality, workflow performance, and business utility together.
- Eligible coverage: The percentage of targeted records receiving at least one acceptable candidate value.
- Automatic acceptance rate: The share of candidates meeting the policy for automatic write-back.
- Reviewer acceptance rate: The percentage of queued values approved by human reviewers.
- Conflict rate: The share of lookups where approved providers return materially different values.
- False-match rate: The percentage of reviewed records associated with the wrong person or company.
- Stale-record rate: The percentage of targeted fields exceeding their refresh interval.
- Cost per accepted update: Provider and workflow cost divided by values that survive validation.
- Rollback rate: The percentage of automated changes later reversed or corrected.
Review these metrics by field and provider. A provider may perform well for company domains but poorly for job titles. Aggregate reporting can hide that distinction.
Set spending limits before enabling fallback calls. For instance, stop after two providers unless the record belongs to a high-priority segment. This keeps enrichment cost aligned with expected value.
Practical Next Steps
A safe pilot should be narrow, reversible, and measurable. Avoid launching across your entire CRM. Use this sequence instead.
- Choose one segment. Start with active target accounts, qualified inbound leads, or another group tied to a current revenue workflow.
- Select three to five fields. Favor missing company attributes before sensitive contact details or lifecycle properties.
- Document field ownership. Identify which values are first-party, provider-supplied, user-entered, or system-generated.
- Define source precedence. List approved providers, freshness limits, identity requirements, and tie-breaking rules for every field.
- Set confidence gates. Separate automatic updates, review cases, and rejected candidates using field-specific thresholds.
- Restrict permissions. Grant access only to the objects and properties required by the pilot.
- Create an exception queue. Show reviewers the current value, proposal, evidence, source dates, and escalation reason.
- Enable logging and rollback. Save old values, workflow versions, provider responses, and batch identifiers.
- Set cost limits. Cap provider fallback, daily requests, and spending by segment.
- Run in suggestion mode. Compare proposed changes with human decisions before allowing automatic write-back.
- Review pilot metrics. Expand only when accuracy, cost, reviewer workload, and rollback rates meet your targets.
Before launch, test duplicate handling, provider downtime, partial responses, malformed values, rate limits, and CRM API failures. Confirm that retries cannot create repeated or conflicting updates.
If your team needs help defining ownership, governance, and success measures, explore AI agent strategy before expanding the pilot.
Frequently Asked Questions
What is CRM data enrichment?
CRM data enrichment adds or refreshes useful information about contacts, companies, and accounts. A governed process also validates sources, protects trusted values, and records why each update occurred.
How does continuous CRM enrichment work?
Continuous enrichment runs when defined events or refresh intervals occur. It retrieves candidate values, normalizes them, applies validation rules, routes exceptions, and writes only approved changes.
Which fields should an enrichment agent update automatically?
Start with reversible, low-risk fields that are empty and supported by strong identity evidence. Industry classifications and standardized employee bands may qualify. Verified emails, consent, ownership, and lifecycle fields need stricter controls.
How do you prevent accurate data from being overwritten?
Assign trust levels to existing values and require stronger evidence for replacement. Protect recent first-party data. Store source dates and route conflicting changes to review.
How should conflicting sources be resolved?
Use field-specific source precedence, freshness, identity strength, and provider agreement. If no source clearly wins, preserve the current value and create an exception for review.
When is human review necessary?
Use review for ambiguous identities, conflicting sources, protected fields, significant value changes, and candidates below the automatic threshold. Review should focus on exceptions rather than every lookup.
How can RevOps control enrichment costs?
Limit enrichment to valuable segments, set refresh intervals by field, and cap provider fallback. Track cost per accepted update rather than cost per lookup.
Further Reading
- HubSpot data enrichment guide explains manual, automatic, and continuous enrichment options.
- Sim’s enrichment agent comparison reviews retrieval, normalization, validation, human review, and CRM write-back patterns.
A dependable enrichment system is not defined by how many fields it fills. It is defined by how carefully it decides what deserves to change. Start with reversible updates, explicit rules, visible provenance, and a narrow pilot. Then expand only when the evidence supports it.
Want this converted into an AI workflow?
Share the workflow, team, or bottleneck you want to fix. Agentix will route it into CRM and follow up with a practical implementation path.